A bare Claude model beat 6 of 10 AI support agents in G2's test; Yuma AI led accuracy at 97%
G2 now grades AI customer-service agents on outcomes rather than demos, and a Y Combinator-backed independent leads the trust metrics. Most packaged rivals, including two listed incumbents, scored below a bare Claude model on the same tasks.
 Richard Tangthree-minute read
G2, the software-review site, has started grading AI customer-service agents the way an auditor grades a new hire: identical tasks, a simulated company, and a machine check that the refund actually happened 1. In G2's current standings, Yuma AI, a Y Combinator-backed Boston startup whose agents resolve ecommerce tickets inside Gorgias and Zendesk helpdesks, ranks first of ten agents on accuracy at 97% and second overall 12.
It also leads policy compliance at 95%, the score that decides whether a brand can let software issue refunds at all 12. The finding that reaches beyond Yuma sits lower in the table: a bare Claude model with no support product around it outscored most of the packaged agents 12.
The refund has to actually happen
G2 built a simulated support company with realistic order data, a written policy and 38 working tools for refunds and account changes, then gave every product the same 50 tasks 1. Language-model judges scored whether each answer was supported by evidence and followed the written policy, and deterministic checks confirmed the required outcome happened in the systems 1. Vendors could flag setup mistakes but could not change their scores 1.
Most products add nothing the model lacks
The most telling row is not a product. A raw Claude Haiku 4.5, Anthropic's$350B — Anthropic, private, latest valuation $350B model with no support product around it, finished ahead of six of the ten agents on task success 2.
A bare Claude model outscores six of ten packaged support agents on G2's task test
Four products beat the raw Claude baseline; Yuma leads them on accuracy and compliance
Data
| Value | |
|---|---|
| Retell | 243 |
| Yuma | 240 |
| LiveAgent | 240 |
| Chipp | 238 |
| Claude Haiku 4.5 (model baseline) | 233 |
| Tidio | 219 |
| BoldDesk | 218 |
| GPT-4o Mini (model baseline) | 210 |
| Zoho | 203 |
| Jotform | 174 |
| HubSpot Breeze | 93 |
| Freshworks | 85 |
Retell, a voice platform that also tops G2's separate voice ranking, leads the table with weaker trust scores than Yuma 23. Yuma's design likely explains that split. Its agent follows a written handbook, runs under hard caps on refunds and coupons, and hands the ticket to a person wherever the handbook is silent 14.
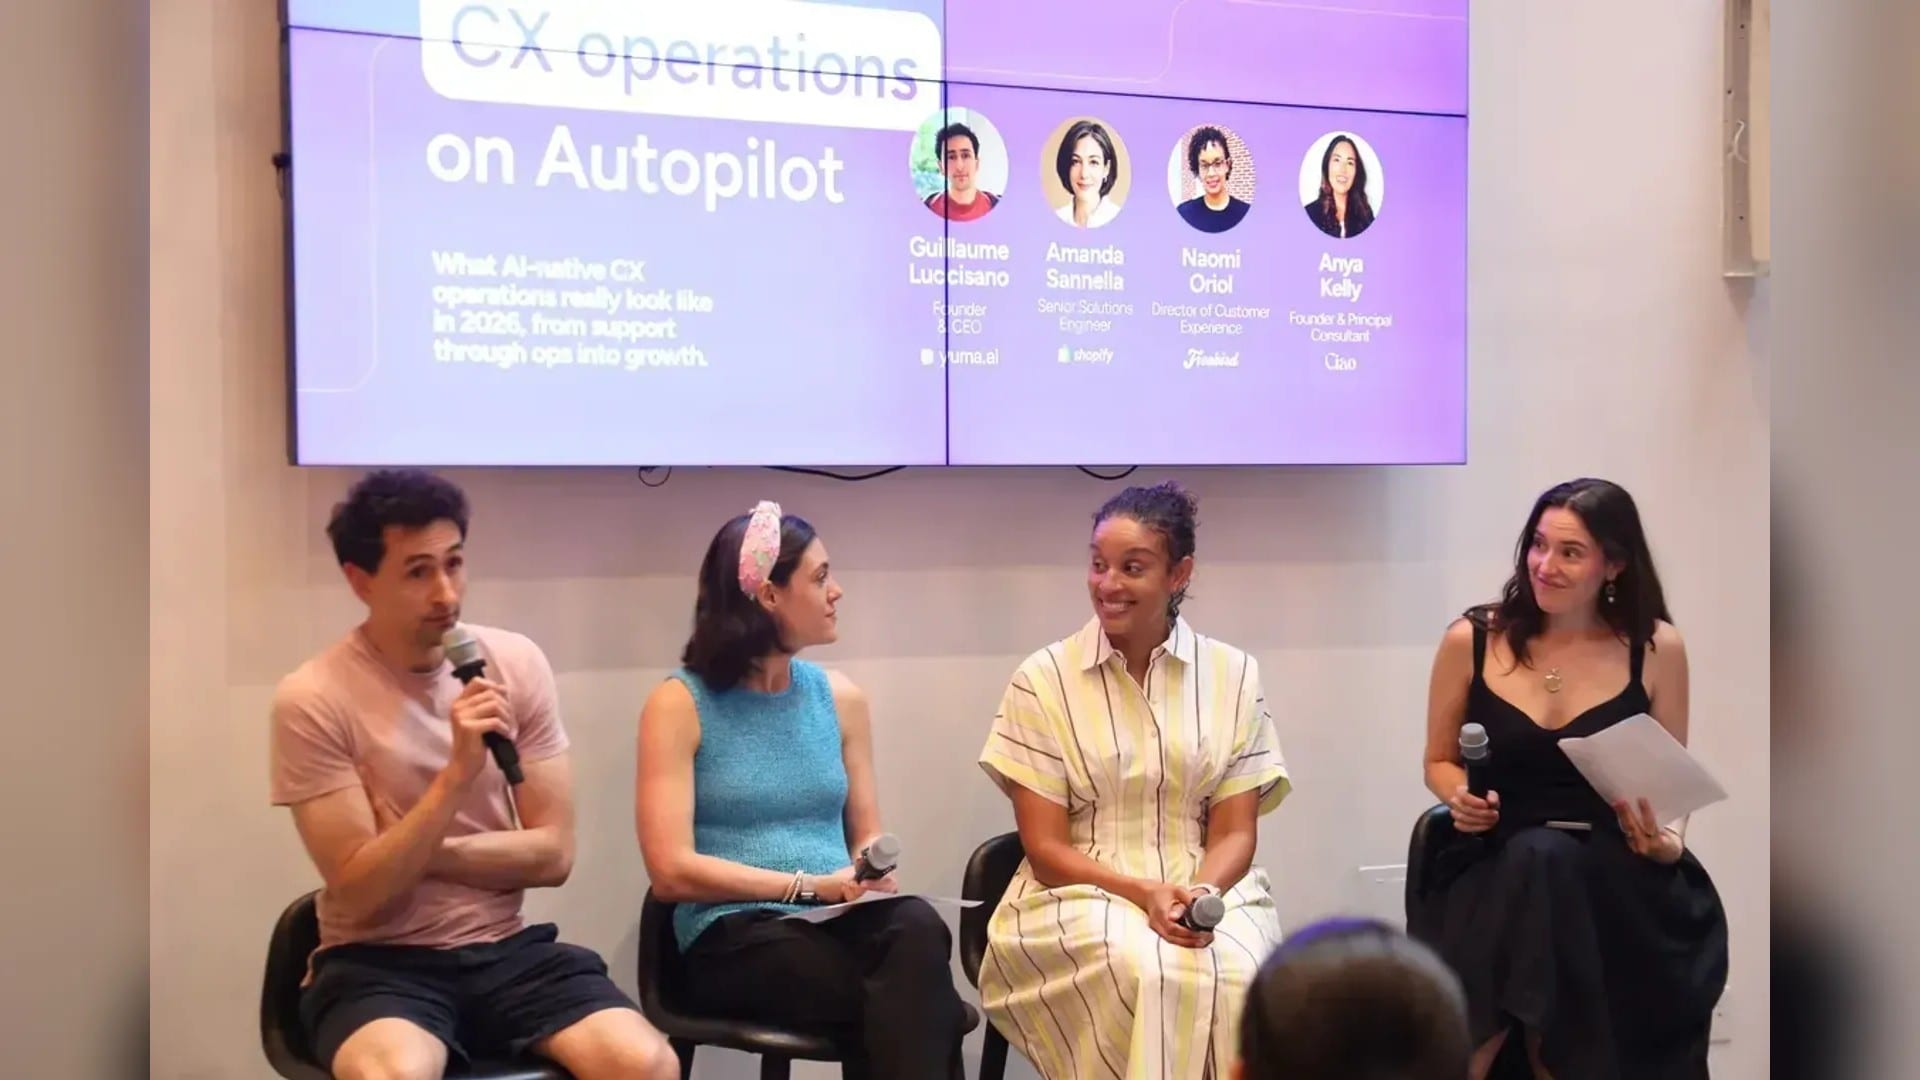
The handoff probably also explains the three-point gap to Retell: passing on a task costs points, while guessing costs a refund nobody authorized 12. As Yuma's founder and CEO Guillaume Luccisano puts it, support leads "lose sleep over the ones it answers wrong: the refund outside the return window" 1.
The giants have not sat the test
A November 17, 2026, buyer's guide counts 44 AI-native support platforms, a market consolidating under bigger owners 5. Zendesk bought Forethought; NICE, a contact-center software giant, bought Cognigy, an enterprise AI platform; SoundHound−8.93% — SoundHound, down 8.93 percent today, a voice-AI company, bought LivePerson 5.
The listed companies this story touches, Salesforce−0.18% — Salesforce, down 0.18 percent today, HubSpot+2.91% — HubSpot, up 2.91 percent today, Freshworks−1.79% — Freshworks, down 1.79 percent today, NICE and SoundHound, have no equivalent result on the board 2. HubSpot's and Freshworks' agents sit at the bottom of the table, while the verified trust headline belongs to a private independent paid only for tickets it fully resolves 125.
The board is still filling in
The November standings are already G2's second published run at this market: October's covered nine agents on 46 tasks, November's moved to ten agents on 50, and G2 plans to refresh results several times a year 16. The gaps are the watchable part. Zendesk, Gorgias and Forethought are marked under evaluation; Decagon~$1.5B — Decagon, private, latest valuation ~$1.5B, a rival support-agent maker, declined; Salesforce and Sierra, an AI support startup, have not been evaluated 2.
Yuma's homepage carries the freshest line in the file: G2 "tested Yuma again on a retail task set", a run whose results are not yet published 4. Support budgets are likely to follow the agents that can show compliance on someone else's test, and the retail run is the next check on whether Yuma's lead holds.
Get Applications by email, free
How AI is changing the software people and companies use. In our daily email, every weekday.
Reader comments
0 comments