Intel and Qualcomm are reported in talks for Tenstorrent worth up to $10 billion
The performance claims beneath reported Intel and Qualcomm bids for the chipmaker are vendor-published, and any bidder can now test them at token price before signing.
 Richard Tang · 3 min read
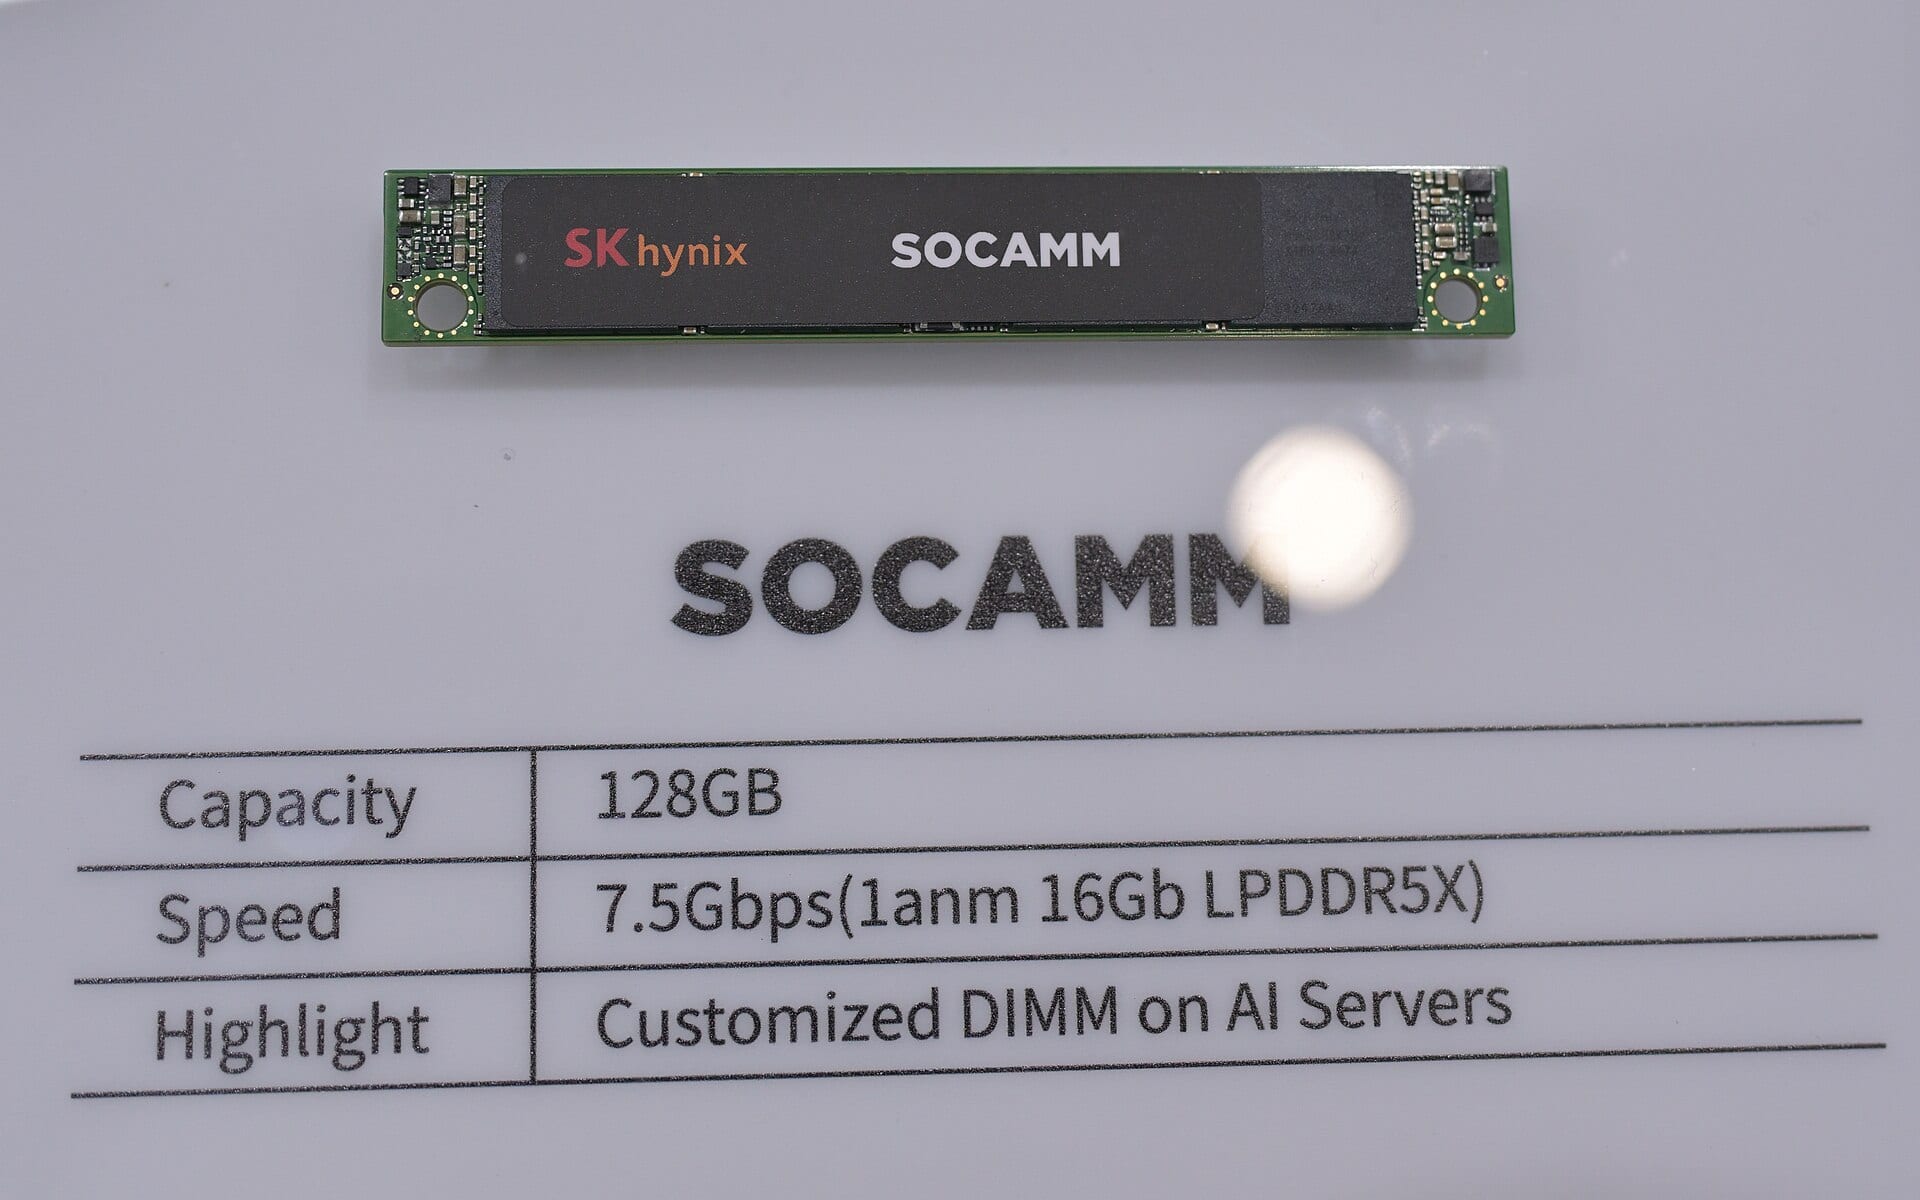
Real-time voice AI got a price tag this month, and it is low enough to move money. On October 2, 2026, Smallest.ai, a voice-AI research lab, put its Lightning V2 speech model on Tenstorrent's~$2.6B — Tenstorrent, private, latest valuation ~$2.6B Galaxy Blackhole servers, on usage-based pricing with no upfront commitment 1. The engineering paper behind the launch claims the same workload runs for roughly a quarter of the accelerator cost of an Nvidia−1.59% — Nvidia, down 1.59 percent today L40S 2.
The claim is vendor-published and unverified, which is exactly why it matters. Intel−6.29% — Intel, down 6.29 percent today and Qualcomm−3.81% — Qualcomm, down 3.81 percent today are reported to be bidding as much as $10 billion for Tenstorrent, a price any bidder can now test before signing 34.
The price break had to be engineered into the model
Tenstorrent's advantage starts in arithmetic. Its Blackhole chips run BlockFloat8, an eight-bit number format, natively on silicon that lists near $1,000 a device, while the paper's authors note that GPUs with native support for the format sit near $40,000 5. Speech is the hard case: text-to-speech models generate continuous waveforms, and small numerical errors compound across denoising steps into audible artifacts 2.
Smallest.ai rebuilt Lightning V2 so that more than 80% of the model runs in that eight-bit format, using the chip's internal memory network to cut data movement, and the audio held: a 0.071 perceptual-score gap against the L40S, which the authors call minor variation 25.
The fleet-scale discount is partly projection
At fleet scale, 550 simultaneous five-second requests, the authors price the workload at about $100,000 of L40S cards or about $27,000 of Tenstorrent P100s 5. The P100's latency figure, though, is carried over from measured P150 results, so the cheaper fleet number rests partly on unmeasured latency 5. Layers too numerically sensitive to quantize, and a compiler not yet fully tuned, mark where measurement ends and projection begins 5.
One voice workload, two bills: $100k of L40S or $27k of Tenstorrent P100s
- Estimate
Data
| Value | |
|---|---|
| Nvidia L40S (estimate) | $100k |
| Tenstorrent P100 (estimate) | $27k |
| Tenstorrent P150 (estimate) | $37k |
Japan repeated the pattern on language models
Japan supplied a second data point the same day. Fixstars, a Tokyo performance-engineering firm, and Macnica, a Tokyo-listed chip distributor (TSE: 3132), tuned the open-weight gpt-oss-120b model on a Tenstorrent workstation 67. A key matrix-multiply step ran 3.68 times faster, and per-token generation time fell from 144.85 to 99.49 milliseconds, a 31 percent cut 6. Porting models onto this silicon is already a billable service Macnica sells 7.
The bids price a token nobody has independently measured
Tenstorrent reached general availability with Galaxy Blackhole on April 28, 2026, and raised a $1.29 billion Series E that August 48. Bloomberg reported Intel and Qualcomm in early talks at $5 billion or more, and The Information, since confirmed by Reuters, put a Qualcomm deal at $8 to $10 billion; no deal has closed 34. Nvidia's AI silicon generates margins above 70 percent, and a cost break that survives verification is the arithmetic that would compress them 4.
Verification is the open link. Comprehensive independent benchmarks of Tenstorrent on production workloads do not yet exist, and Bernstein analyst Stacy Rasgon warns that a buyer may be acquiring Tenstorrent chief executive Jim Keller, an architect with a record of leaving big companies within a few years 4. Any bidder can now run the workload and read the invoice before signing, and that invoice will settle the argument.
Deepdive
AI-generated from this story and its cited sources. Not investment advice.