OpenAI cuts flagship pricing 20% to match Anthropic as heavy users call GPT-6.2 Astra unusable
OpenAI cut its flagship's price to match Claude Fable 5.2's rate, and the users who run models hardest rejected it, 24 hours before Anthropic priced a $1.4 trillion IPO on the assumption the quality gap holds. The independent labs say the gap is real, for now.
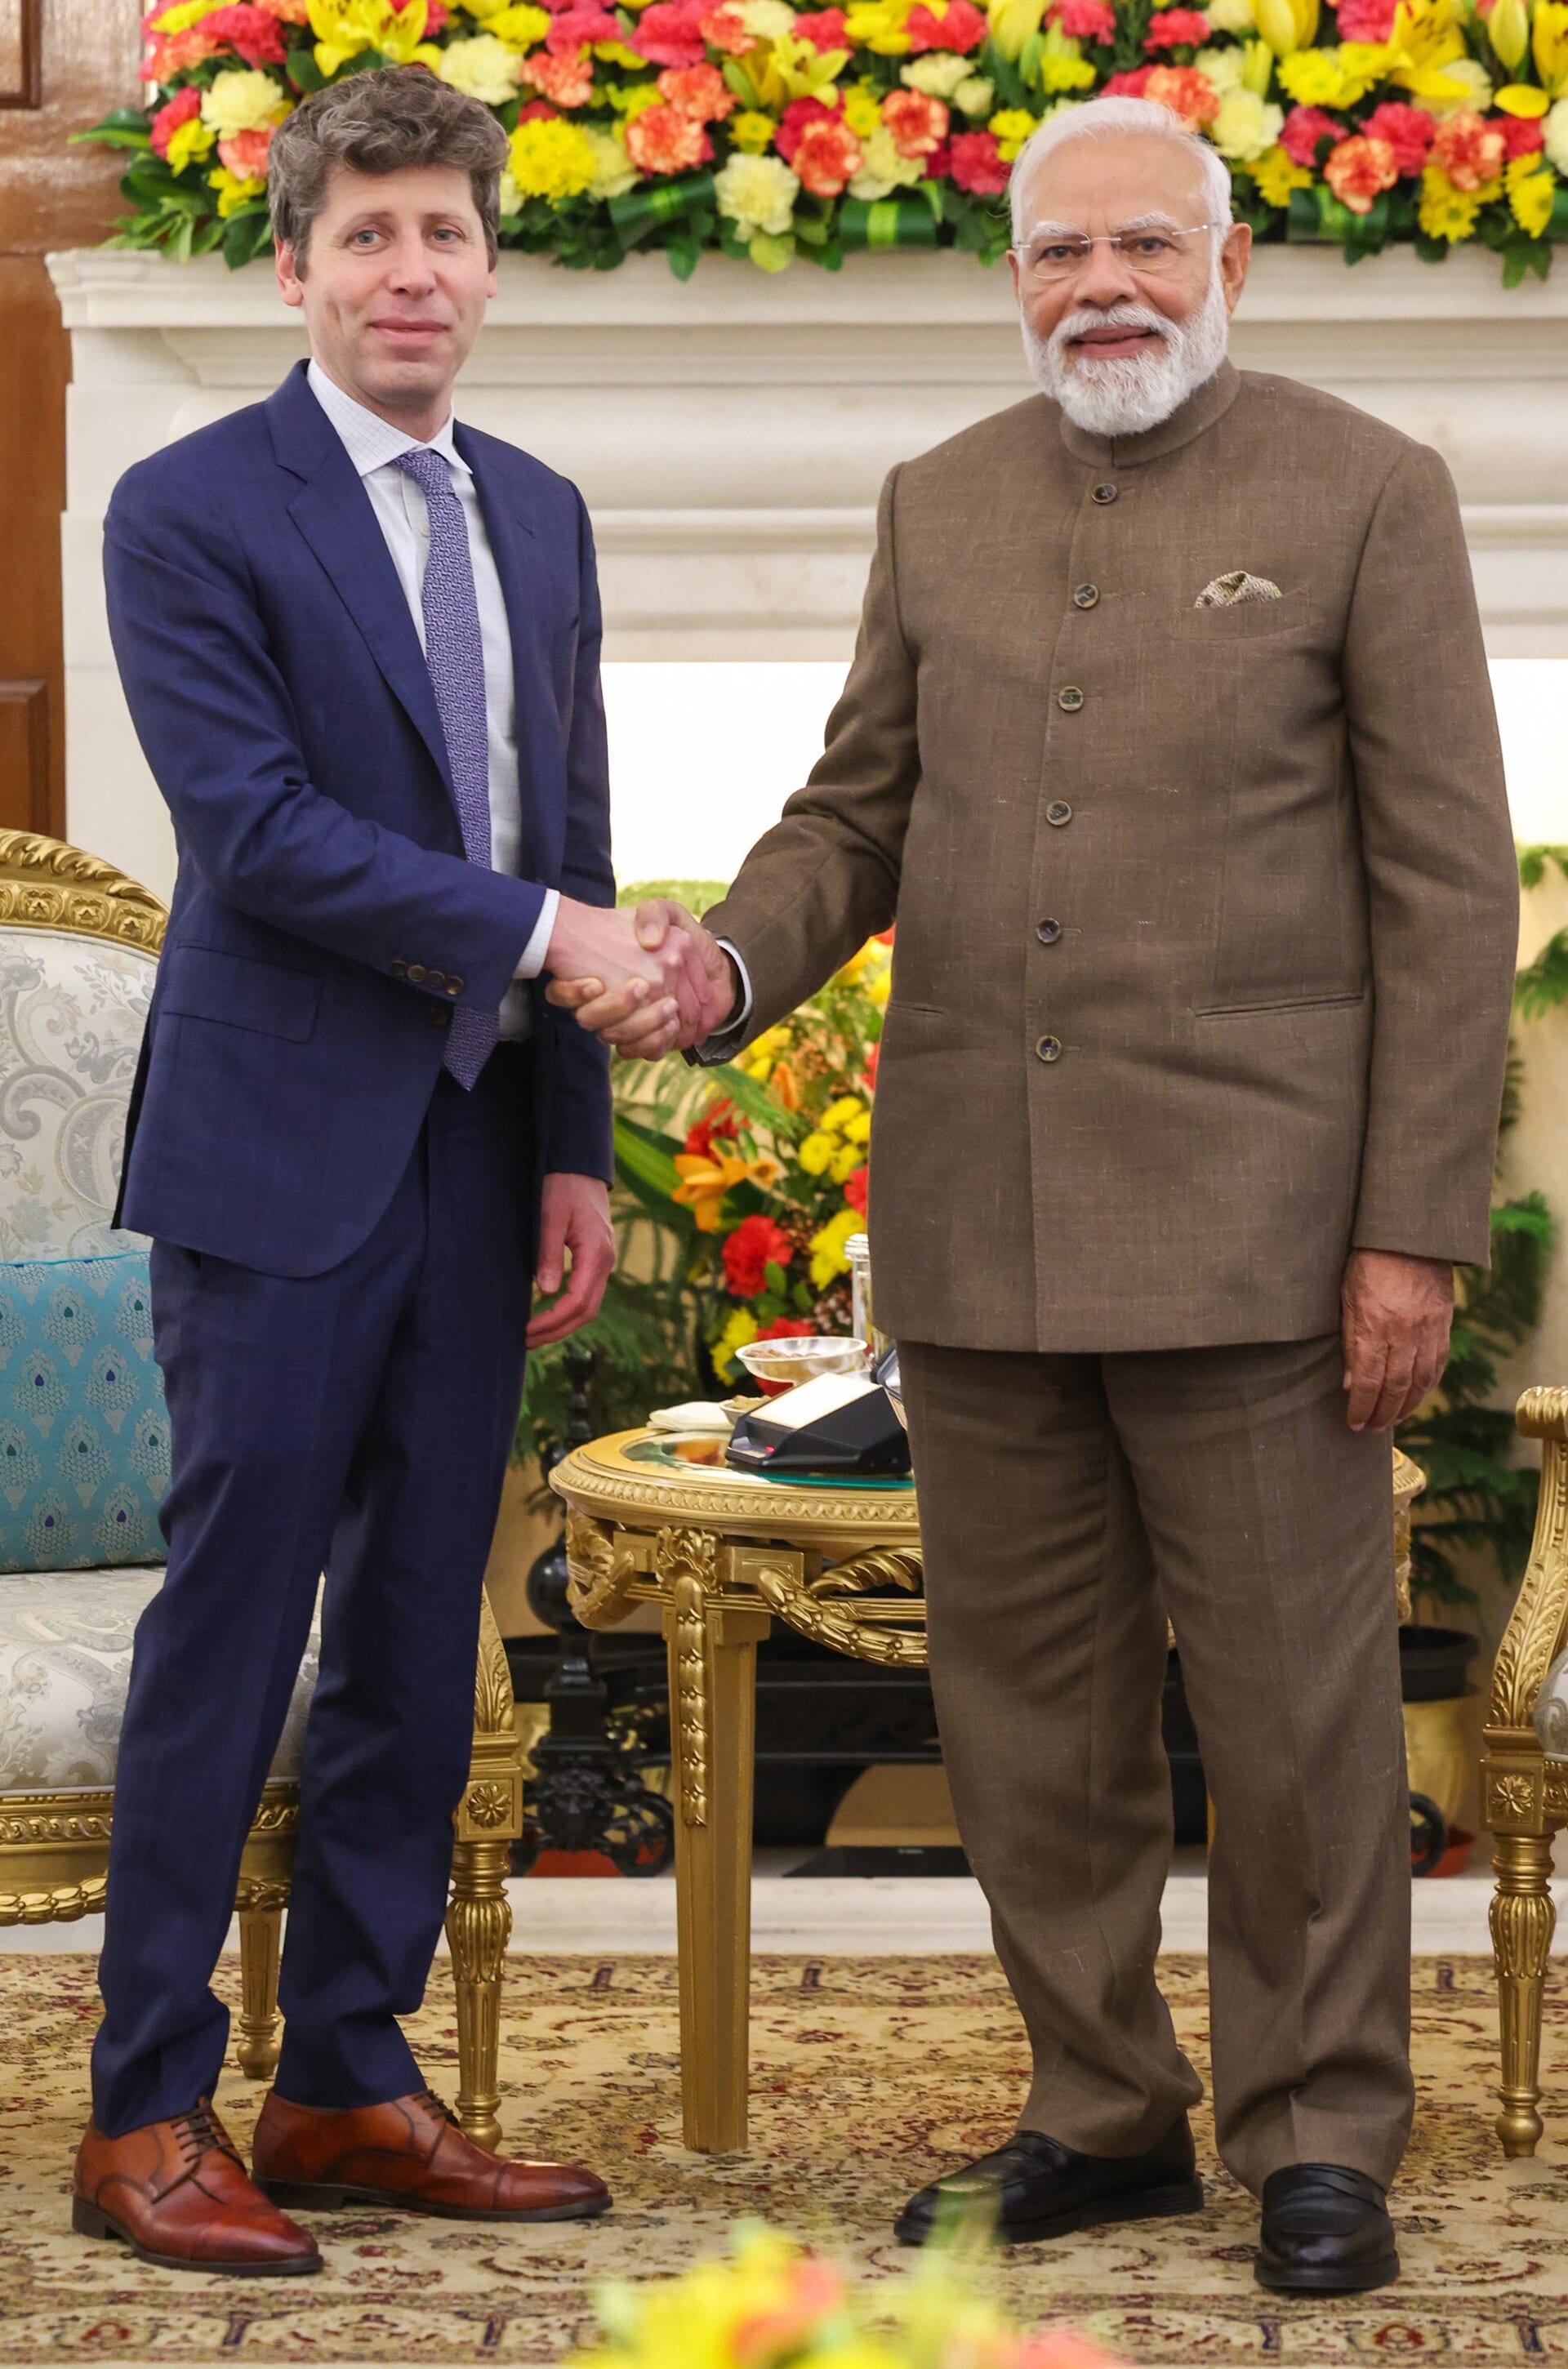
 Vincent Jiangthree-minute read
OpenAI$1.18T — OpenAI, private, latest valuation $1.18T shipped two models on November 17: GPT-6.2 Astra, its flagship for professional work in science, law and finance, and GPT-6.2 Sol, the cheaper everyday model 12. Astra's API price fell 20% to $8 per million input tokens and $40 per million output tokens, exactly the rate Anthropic$350B — Anthropic, private, latest valuation $350B charges for Claude Fable 5.2 12.
The users who run models hardest were not buying it. Investor Matt Shumer called Astra "essentially unusable"; developer Theo Browne called it "the worst model OpenAI has ever released" after seven days of delegated work left his experimental Rust compiler rewrite running 56% slower 1. Wharton professor Ethan Mollick called it the first OpenAI flagship since GPT-4.5 that is not a clear step forward 1.
The IPO prices a premium OpenAI just undercut
One day later, Anthropic was set to price the largest IPO in years: 825 million shares at $70 to $78, more than $64 billion raised, a valuation near $1.4 trillion, with orders around seven times the shares on offer 36.
Trading under the ticker ANT begins Thursday. That price rests on premium-model pricing power, the kind an $8/$40 flagship charges for 2. OpenAI's counter is cost per task: it claims Astra beats Fable 5.2 on the professional-work benchmark Agents' Last Exam by 5.5 points at 5% of the cost 2. The falling price of intelligence we flagged in September is now aimed directly at the premium Anthropic shareholders are paying for 7.
The independent tests still put Fable ahead
Independent testing says the quality gap is still real. On Artificial Analysis' Intelligence Index, Astra scores 62, second to Fable 5.2's 65 24. Coding flatlined: Astra matched its predecessor in the Coding Agent Index and Sol dropped three points 2. At maximum effort, Astra guesses instead of abstaining on 59% of hard factual questions, per Artificial Analysis' hallucination measure 2. Epoch AI ties Astra with Fable at 174 on its capabilities index, but on real research tasks drawn from its own work, neither model met Epoch's employee standard 5.
Claude Fable 5.2 still tops the independent intelligence index
Data
| Intelligence Index score | |
|---|---|
| Claude Fable 5.2 | 65 |
| GPT-6.2 Astra | 62 |
| Gemini 4 Carbon | 60 |
| Claude Opus 5.5 | 59 |
| GPT-6.2 Sol | 57 |
| GPT-6 Astra | 57 |
Astra wins where the work is cheap
Astra's supporters have numbers too. It leads Terminal-Bench-Science, the AA-3D design ranking and robotics, and Artificial Analysis says OpenAI owns the cost-performance frontier, the line where no model is both cheaper and better 2. Testers praised its animated visuals and agentic video editing 1.
But benchmarks score finished tasks; power users complained about staying on task through long delegated work and explaining what it did afterward, exactly the work a trillion-dollar premium is priced on 1.
The first print decides how much the gap is worth
Thursday's ANT debut prices the gap as it stands 36. The bear case for Anthropic is OpenAI's own parity claim landing a release or two from now; until users stop redoing Astra's work, the stumbles defend the premium. Watch whether the stock clears $80 on the first print, and whether OpenAI ships a fix faster than its usual cadence 6.
Get Model by email, free
The AI labs, their models, and the business behind them. In our daily email, every weekday.
Reader comments
0 comments